
Associate
January 22, 2024
Question

HAL_Delay() affecting function execution times

  • January 22, 2024
  • 2 replies
  • 2273 views

Hi,

I'm trying to measure the execution time of an algorithm using the Cortex-M7 on a Nucleo-H745ZI-Q. I'm measuring the execution time using a GPIO pin and the DWT cycle counter register. Here's the form this profiling takes in my while (1) loop.
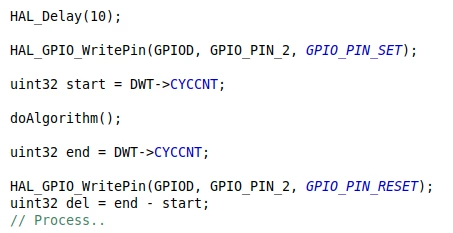
stn_3-1705884655731.png

I'm seeing some unexpected behavior when running experiments with different optimization flags:

  • When I compile with the -O3 flag, I'm seeing the execution time of the algorithm roughly half when I remove the call to HAL_Delay() (observed on the scope, and number of cycles).
  • When I compile with the -Ofast flag, I'm seeing the execution time of the algorithm roughly double when I remove the call to HAL_Delay() (observed on both scope, and number of cycles).

I'm changing the optimization flags through the project properties -> C/C++ build -> Settings menu in the STM32CubeIDE. The algorithm is utilizing CMSIS DSP instructions. I'm not seeing this behavior when doing the same thing on a NUCLEO-G491RE. What steps should I be taking to figure out what's causing this weirdness?

TIA,

stn

    This topic has been closed for replies.

    2 replies

    TDK
    January 22, 2024

    The M7 core is considerably more complicated than the M4 core. Instructions can be parallelized, cache is better. You cannot count on a particular instruction always taking X cycles like you can (more or less) on the M4.

    Note that setting pins is fast, but it's not an atomic one-cycle call. There is a delay between WritePin and when the pin actually goes high. Small, but it's there. This delay will be larger if other instructions are in the pipeline. Consider using DSB to ensure the write is complete, but you should still expect execution time to vary based on what else is going on within your program.

    "If you feel a post has answered your question, please click ""Accept as Solution""."
    stnAuthor
    Associate
    January 22, 2024

    Although, even when I remove my calls to HAL_GPIO_WritePin, I'm seeing the same behavior. And I would assume reading from CYCCNT would almost be atomic.. @TDK, are you suggesting that reading from a CYCCNT could take >15ms longer if compiled with compiler optimization, because of how the Cortex-M7 queues instructions in parallel? How can I accurately measure the execution time of programs on the M7 in this case?